🗂️ This experiment is a project conducted at Markr.AI.
🥇 Go to the CSAT LLM leaderboard benchmark
🪑 Go to the 2023 CSAT mini-benchmark tutorial
GPT 2025 CSAT LLM Benchmark Evaluation Results
| Rank | Model | Raw Score | Estimated Grade Cutoff (as of 2025.11.18) |
|---|---|---|---|
| 🥇1st | o1-Preview | 97 | Grade 1 |
| 🥈2nd | o1-mini | 78 | Grade 4 |
| 🥉3rd | gpt-4o | 75 | Grade 4 |
| 4th | gpt-4o-mini | 59 | Grade 5 |
| 5th | gpt-3.5-turbo | 16 | Grade 8 |
o1-preview scored 97 on the 2025 CSAT Korean Language section! While creating the leaderboard and conducting experiments, we were able to assess the language level of LLMs, and achieving a performance where it got only one question wrong and answered everything else correctly is an astonishing result. It answered all but one of the Korean Language questions from the CSAT, the most authoritative assessment of Korean language proficiency.
In the previous 10-year CSAT Korean Language LLM leaderboard, a performance comparison showed that gpt-4o, which took first place, averaged around Grade 3, with a top score of 86. It was clear that LLMs still had a long way to go before matching human language ability.
However, on the 2024 CSAT, o1-preview achieved 88 points and Grade 1, showing language ability comparable to that of humans. But its near-perfect score of 97 on the 2025 CSAT demonstrates that the time when LLMs surpass human performance in Korean language ability is not far away.
🤷 What was the one question o1-preview got wrong?
The question o1-preview got wrong was Question 8 (3 points), a non-literary reading passage
- The question o1-preview got wrong was Question 8 (3 points), a non-literary reading passage that required a detailed logical comparison between the passage and the answer choices.
- We experimented with and applied a prompt that allowed us to see the basis for o1-preview’s answer by having it write the reasoning behind its judgment for each choice. o1-preview goes through a complex logical reasoning process called CoT, but due to the nature of the question, it made an error in understanding the context of the passage and the choices and identifying the implicit intent based on that understanding.
- The correct answer was 1, but o1-preview selected 3.
- Interestingly, Question 8 also had the highest wrong-answer rate among test takers on the 2025 CSAT (81.5%). Reference: EBSi CSAT Korean Language wrong-answer rate
🪑 Background and Purpose of the Benchmark
The benchmark began with the project Let’s Achieve Grade 1 in CSAT Korean Language with an LLM at Nomadamas!. It was a project to take on KICE, which creates the notoriously difficult CSAT Korean Language exam, through prompt engineering, which was highly popular when GPT-4 was first released.
Nomadmas’s project focused this time on comparing the performance of LLM models, based on high-quality prompts developed through numerous prompt engineering experiments. Accordingly, we created a leaderboard to determine which of the models released so far performs best based on 10 years of CSAT Korean Language exams, and it became the CSAT Korean Language LLM leaderboard.
The main purposes of the project are as follows.
- Sharing benchmark information that can be used to compare Human performance and LLM performance
- A carefully selected benchmark dataset from KICE, Korea’s most authoritative institution for evaluating Korean language proficiency
- Preventing data leakage with a new CSAT Korean Language benchmark dataset updated every year
- Enabling an open-source LLM not dependent on any particular country or company to achieve Grade 1 on the Korean CSAT
🧪 Experimental Method
1️⃣ Dataset Construction and Parsing:
We collected 10 years of CSAT Korean Language data from 2015 to 2024. We extracted only the text from the CSAT Korean Language PDFs and parsed the extracted text into JSON by separating it into
- Questions
- Passages
- Reference materials
- Answer choices
When referring to a specific word, paragraph, or sentence such as [A] or [B], we indicated that section by enclosing it in parentheses. In cases involving tables or images, we directly replaced them with explanatory text describing the relevant material.
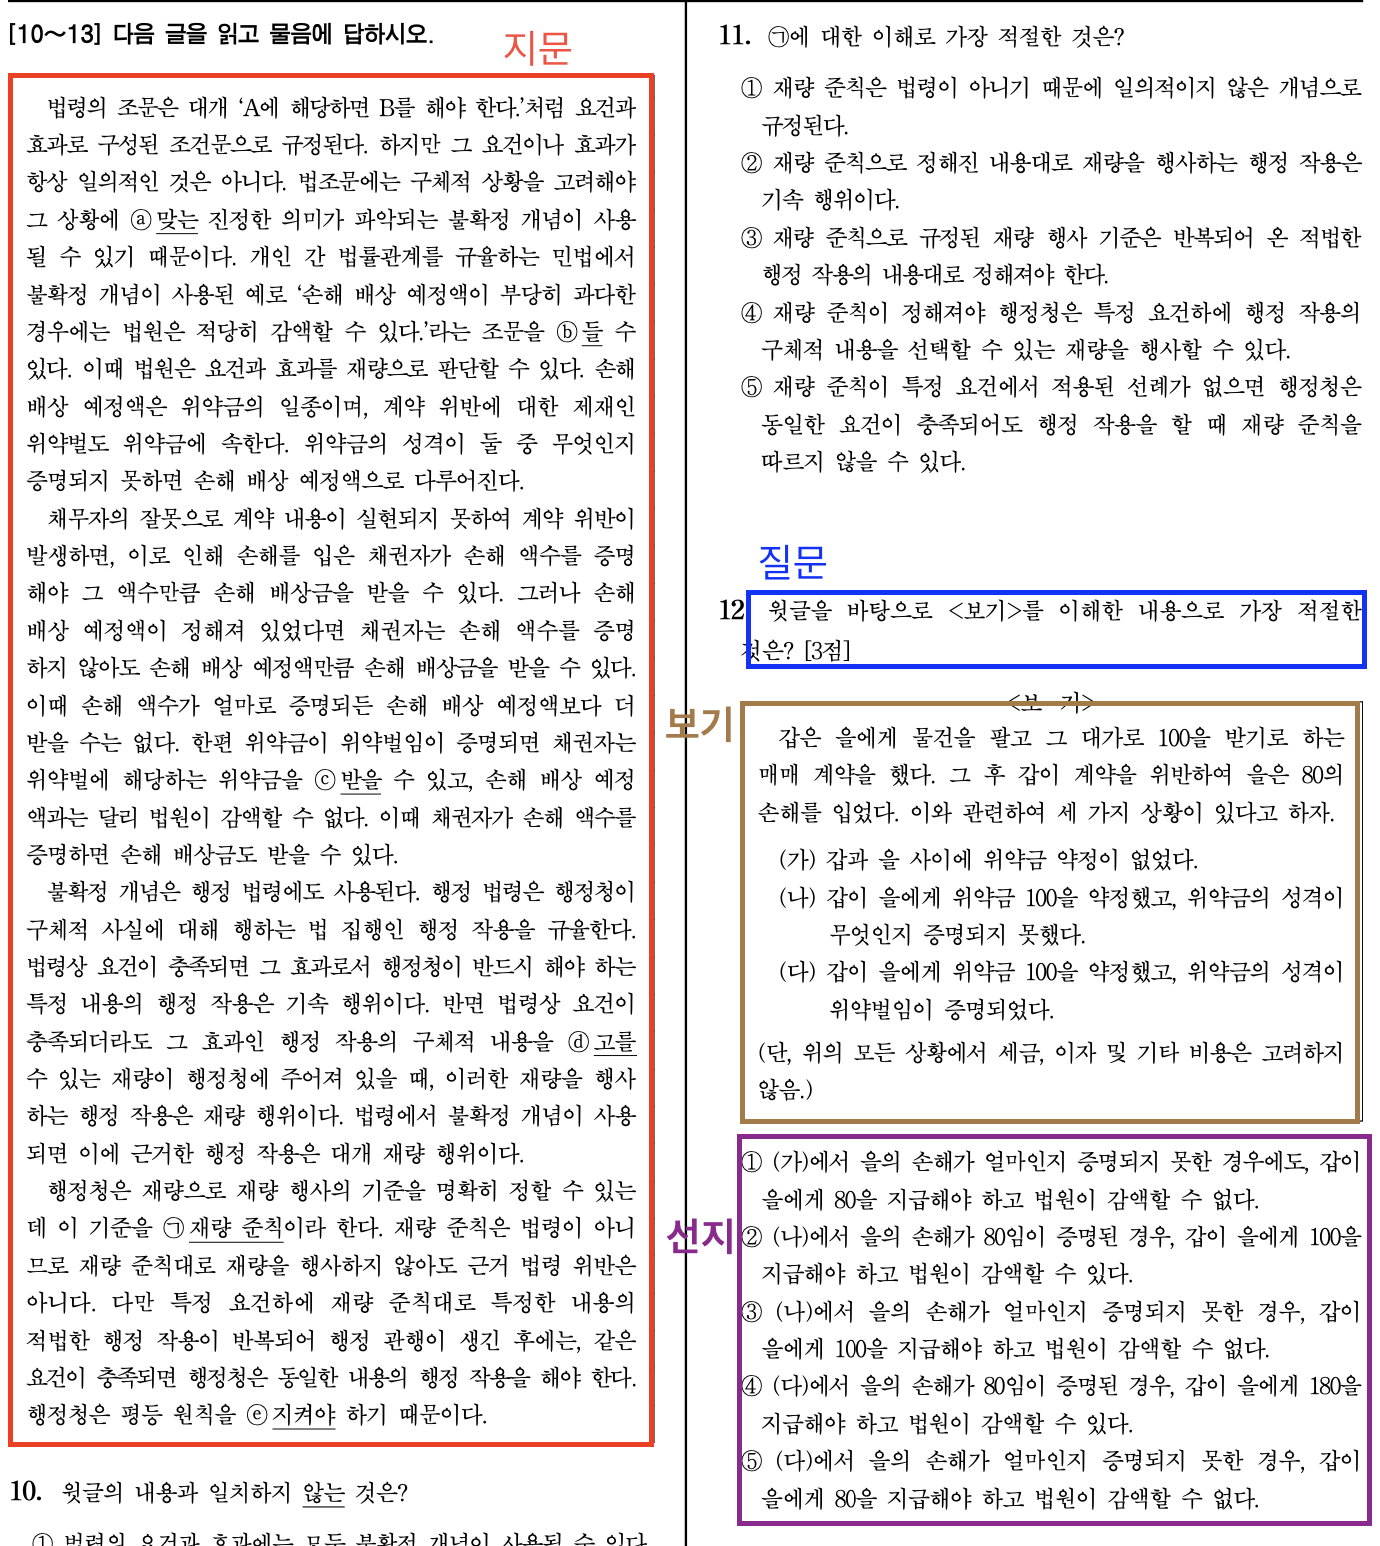
Based on the created JSON files, we parsed the data into qa and corpus to create data for AutoRAG.
For more details about the dataset construction, please refer here
2️⃣ Benchmark Using AutoRAG:
AutoRAG automatically optimizes the optimal RAG pipeline to fit the data you use.
Among AutoRAG’s supported features, we used it for this CSAT benchmark leaderboard because its YAML-file functionality provides convenient access to various models and its GOAT feature allows prompts to be swapped easily.
We also added a mini-test feature that lets you check the performance of models you are curious about using the 2023 CSAT, so if you are interested, please check out the CSAT benchmark mini-test!
3️⃣ Evaluation
In the competition, we measure whether each model’s submitted answer to a given question matches the actual correct answer. When the model provides its final answer according to the previously defined answer format, the LLM extracts the answer from it. The extracted answer is graded against the answer key created previously, and the final score is calculated.
4️⃣ Scoring and Leaderboard Construction
The leaderboard rankings were determined by the average standard score, which reflects the difficulty of the questions for each year.
🎬 Future Direction
-
We plan to continuously evaluate LLMs released up to each point in time in accordance with the schedule of the Korean CSAT and mock exams—that is, LLMs with no opportunity to learn newly released questions, preventing data leakage.
-
The goal is to enable an open-source LLM not dependent on any particular country or company to achieve Grade 1 on the Korean CSAT
🏝️ Thought Land
- We were able to confirm that o1 preview possesses the language level and logical ability of the top 4%. This means that LLMs can develop judgment and logical abilities superior to those of humans, while making these intelligent tools more accessible to people.
- This may soon predict the end of white-collar work. Rather than hiring expensive people with the judgment and reasoning abilities of the top 4%, companies will hire cheaper and faster LLMs, posing a significant threat to white-collar workers.
-
- If white-collar work can be replaced solely by GPU costs, most office jobs, including administration, data analysis, and report writing, could be automated.
- As open-source AI advances rapidly, there is a possibility that the prologue to the end of white-collar work will begin within 6 months to 1 year.
- The end of white-collar work could mark the beginning of an era in which AI with superior reasoning and judgment becomes the “boss,” while humans instead perform jobs requiring physical labor that LLMs cannot do. In other words, it could become a social turning point that reconstructs the concept of human labor.