Situation
While preprocessing the RAGchain benchmark dataset, I noticed that retrieval ground truth was assigned to multiple corpus IDs for a single query ID, as shown below.
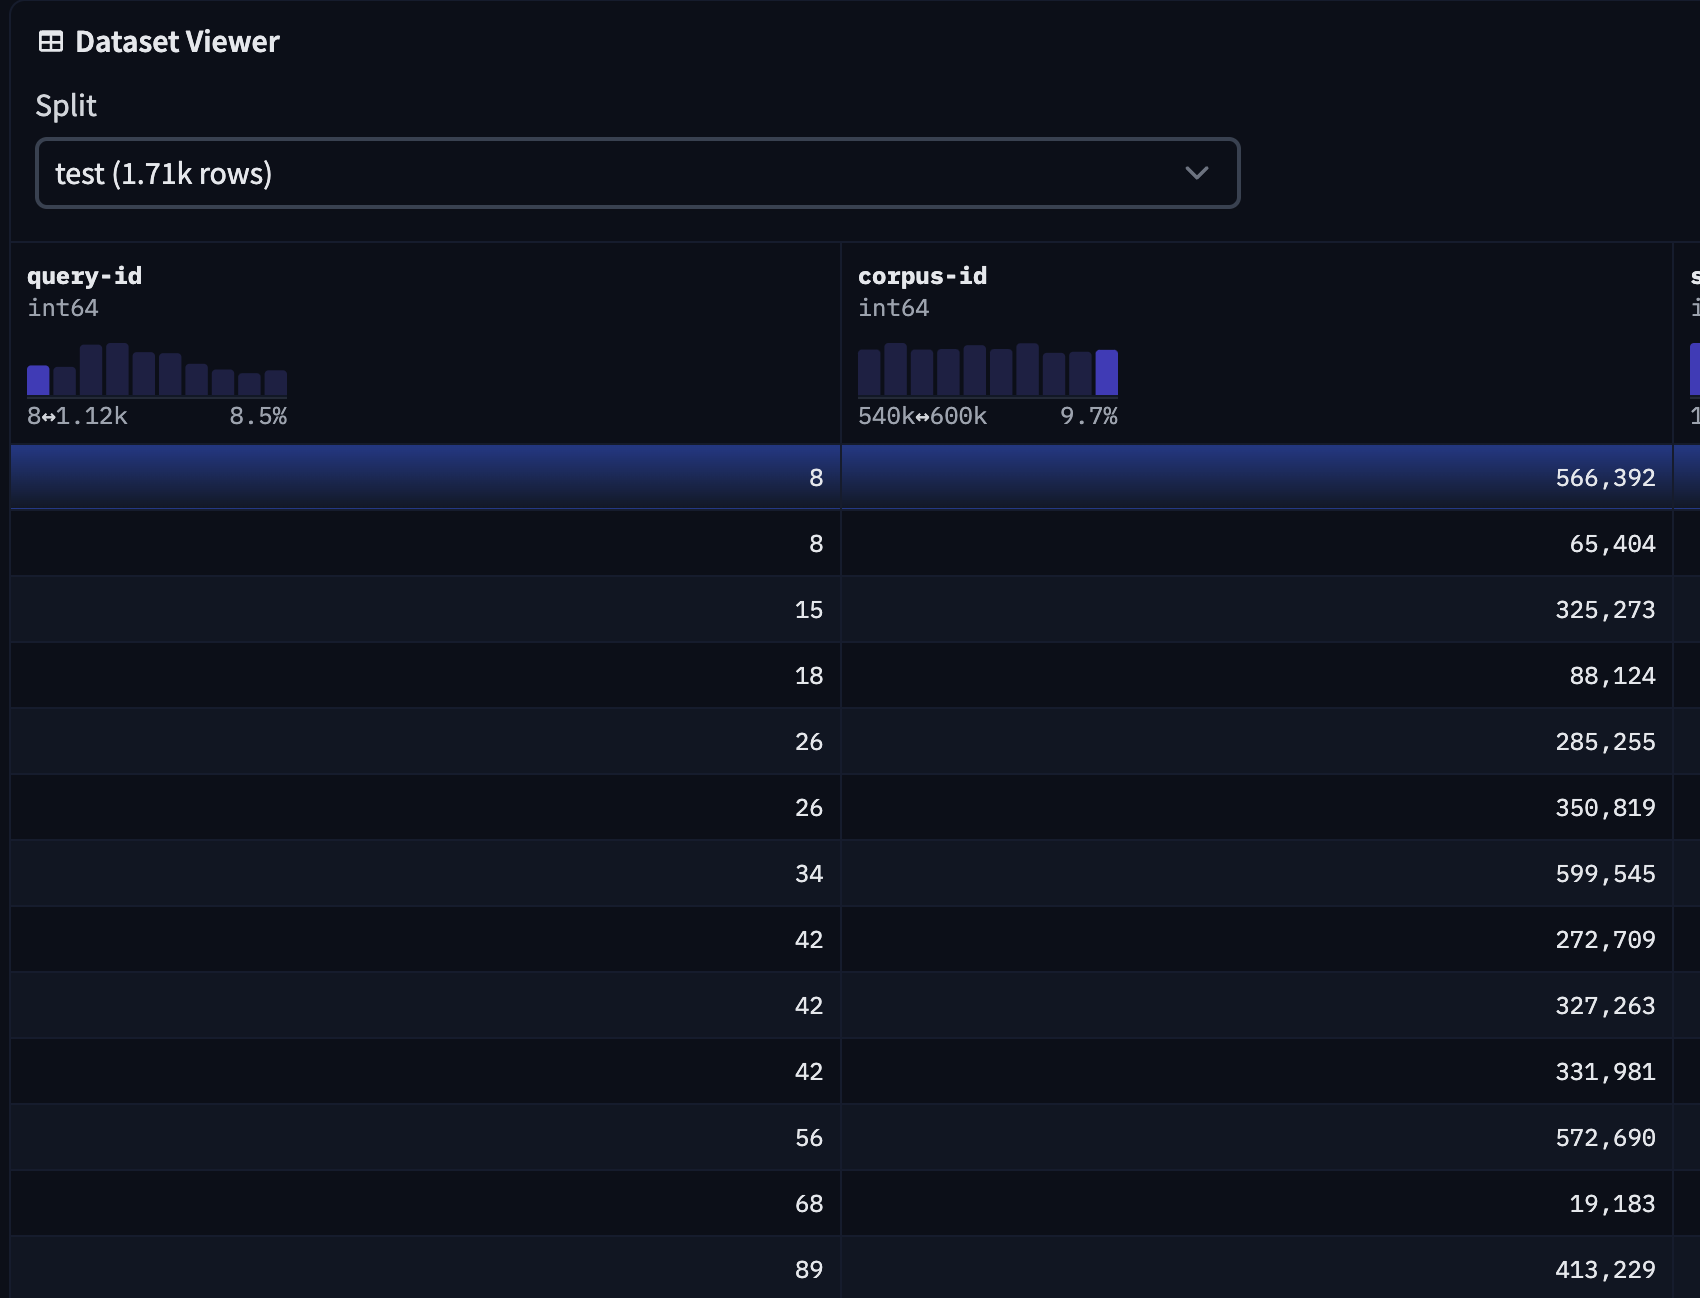
Therefore, I wanted to load this dataset, convert it into a pandas DataFrame, merge the duplicate query IDs using pandas methods, and store the corpus IDs together in a list in a single row.
Solution
self.qrels = self.qrels.groupby('query-id', as_index=False).agg({'corpus-id': lambda x: list(x), 'score': lambda x: list(x)})The self.qrels.groupby('query-id', as_index=False) part groups the DataFrame based on the ‘query-id’ column. as_index=False specifies that the ‘query-id’ column should not be used as the index in the grouped result.
The .agg({'corpus-id': lambda x: list(x), 'score': lambda x: list(x)}) part converts the values in the ‘corpus-id’ and ‘score’ columns into lists for each group. Here, lambda x: list(x) is a function that converts all values in each group into a list.
Therefore, this code groups the DataFrame based on ‘query-id’ and converts the values in the ‘corpus-id’ and ‘score’ columns into lists for each group. This makes it possible to group multiple ‘corpus-id’ and ‘score’ pairs for each ‘query-id’ into a single list.
groupby method
This method groups a DataFrame according to a specific criterion. For example, to group a DataFrame based on a column named ‘query-id’, you can use df.groupby('query-id'). This groups rows with the same ‘query-id’ into a single group.
agg method
This method performs a specific operation on each group. For example, to convert the values in the ‘corpus-id’ and ‘score’ columns of each group into lists, you can use df.groupby('query-id').agg({'corpus-id': lambda x: list(x), 'score': lambda x: list(x)}). This converts the values in the ‘corpus-id’ and ‘score’ columns of each group into lists.
Using these two methods together allows you to perform complex data-processing tasks, such as grouping a DataFrame according to a specific criterion and performing a specific operation on each group.