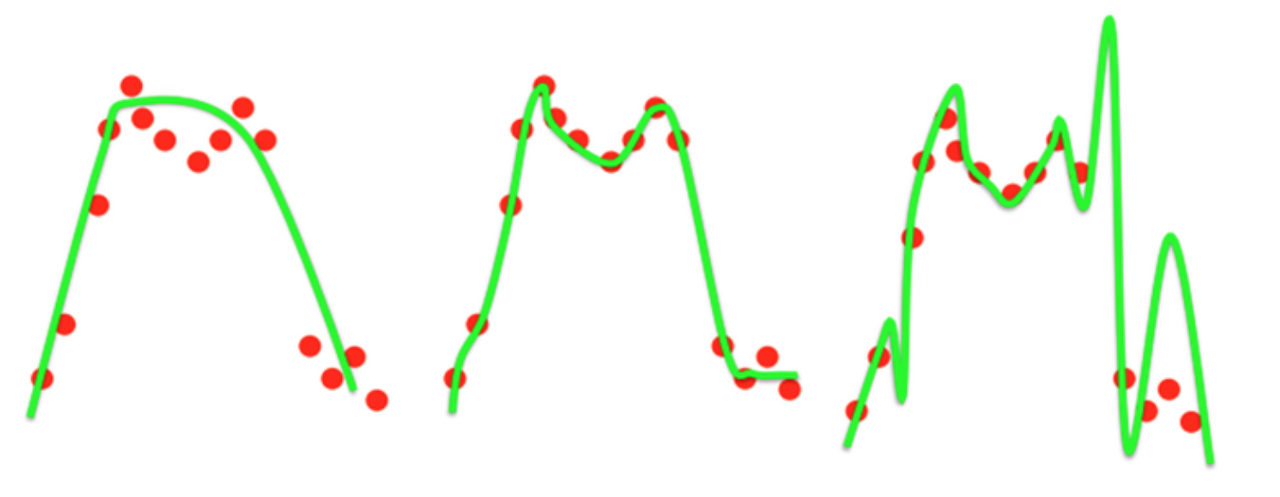
If the same points are given and a function that can represent these points is estimated, the middle is considered optimized.
- The left is called underfitting because excessive simplification causes many errors.
- The right represents the training sample too accurately, so you can see that errors occur for new test samples.
Content and image source: https://22-22.tistory.com/35
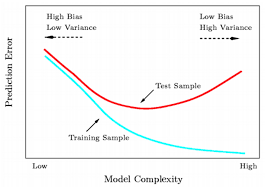 -> Excessive learning of the training sample / As the model becomes more complex, the loss for new test samples initially decreases, but you can see that it gradually increases.
What is overfitting?
In multiple linear regression, excessive learning of the training data causes the prediction accuracy for the training data to become too high, resulting in lower accuracy for new data / the model’s generality decreases. It can also occur when the model’s complexity increases.
How can it be identified?
When the prediction accuracy for new data is very low in a multiple linear regression model trained on past data.
Solutions
-
cross-validation (k-fold is standard)
-
Regularization
- A method for implementing a generalized model by reducing model complexity -> imposes a penalty on the model’s weights (L1, L2 regularization)
- L1 regularization -> makes the weights corresponding to unnecessary features exactly 0
- L2 regularization -> makes the weights for outliers with very large or small values close to 0
- Regression algorithms that apply regularization are classified as Lasso, Ridge, or Elasticnet Regression, depending on the regularization method used
-
data augmentation (increasing the training data)
-
dropout: turn off neurons during training
-
Lower Model capacity: Simplify the model so that it is not excessively complex compared to the training data, such as by reducing the size of the hidden layers or reducing the number of layers.
If Test Set Accuracy increases and then decreases, this can be considered a case of insufficient training data. The amount of training data needs to be increased. For images, the data can be augmented by changing the image’s proportions, covering part of it, or rotating it.
There are cases where the Training Set Accuracy is close to 100% but the Test Set Accuracy is considerably lower. It is necessary to check whether the training data is biased. This may occur when data from special cases is used to solve a general problem.
Content reference: https://22-22.tistory.com/35
What is Underfitting?
A state in which the model has not even learned the existing train set.
Why does it occur?
- The number of training iterations is too small
- The model is too simple compared to the characteristics of the data
- The amount of data is too small
Summary
Overfitting is a phenomenon in which the model is excessively fitted to the train set, causing prediction accuracy for new data to decline and reducing generality.
Further reading link
http://sanghyukchun.github.io/59/
Sources:
- Reference to the content of the Alice intermediate machine learning course
- Overfitting image & image of 3 prediction types:https://22-22.tistory.com/35